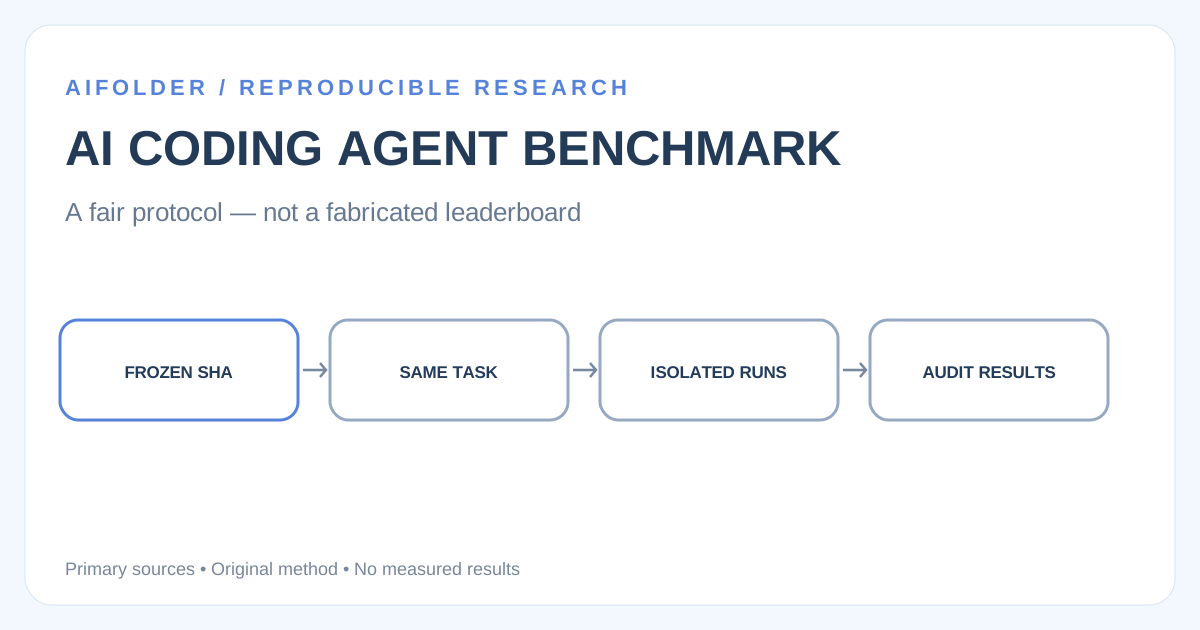
AI DirectoryHow to Benchmark AI Coding Agents Fairly: A Reproducible ProtocolA practical benchmark methodology for comparing coding agents on the same feature, tests and environment—without claiming results that were not measured.AiFolder Editorial Team·Oct 10, 2026·5 min read
AI ToolsMCP Gateway vs Direct MCP Servers: Which Scales Better for AI Agents?Managed MCP gateways promise thousands of tools behind one governed endpoint. We break down the architecture and define a benchmark for latency, permissions, approvals and failure isolation.AiFolder Editorial Team·Oct 2, 2026·9 min read
AI ToolsStrands Decider vs Jev: Can a 2B Model Route AI Agents?Small decision models promise cheaper, faster agent routing than general LLMs. We compare the architecture and publish a reproducible benchmark plan for Strands Decider, Jev and an LLM baseline.AiFolder Editorial Team·Oct 2, 2026·9 min read
AI ToolsJev vs LLMs for AI Decisions: Speed, Cost and AccuracyJev proposes a different path for AI classification and routing: typed decisions with calibrated probabilities instead of generated text. We break down where that could beat an LLM and define an independent benchmark.AiFolder Editorial Team·Sep 21, 2026·8 min read